Gemini决策API:快速、经校准的多模态决策

内容来源:https://blog.google/innovation-and-ai/technology/developers-tools/gemini-decisions-api/
内容总结:
谷歌近日推出Gemini Decisions API,基于全新Gemini Decision 1模型(gemini-decision-1),通过Google AI Studio的Gemini API开放使用。该接口面向工具选择、策略校验、模型路由、上下文分级等有限选项决策场景,支持文本、图像、音频、视频和PDF等多模态输入(最高256K token),单次请求最多可提交1000个独立问题。模型不逐token生成文本,而是单次前向计算为候选选项打分,端到端延迟150至250毫秒,输入token定价为每百万token 0.10美元,输出token不计费。
在智能体路由、推理、排序和多模态理解等基准测试中,Gemini Decision 1整体领先,校准误差最低。其模型计算延迟中位数为50至100毫秒,在16K token以内上下文及1至100个问题的请求范围内基本保持平稳。相比Gemini 3.5 Flash-Lite配合Interactions API,在共享基准套件上成本降低近5倍。
该模型原生支持多模态评估,可在单次请求中混合是/否判断、多项选择和评分量表三类问题,每个答案均附带0至1的置信度分数,便于将模糊情形转交备用流程或人工复核。输入字段沿用Interactions API的Content块格式。
谷歌内部多个团队已将Decisions API用作低延迟控制层:Gemini Notebook将其作为实时路由器,日常查询延迟最高降低40%;Stitch快速画布实验可在数秒内生成可交互的产品流程线框图;Google Labs的CC用其从200多个选项中快速选取表情反应;Google Search则用其检测对抗性行为与内容。
Gemini Decision 1输入token定价为每百万token 0.10美元,输出token免费,Google AI Studio提供免费额度供原型开发。共享输入每次请求仅计费一次,问题数量不影响输入计费,且无输出token、可变思考token及单独音频转写和OCR费用。开发者可通过Google AI Studio获取API密钥,试用相关演示应用,并参考Python、JavaScript和REST文档。OpenRouter、LangChain、Vercel、LiteLLM、Pydantic AI、Pipecat、LiveKit和OpenCode等生态集成正在陆续推出,Google Cloud中的Gemini支持也将很快上线。
中文翻译:
Gemini决策API:快速、校准的多模态决策
今天,我们推出Gemini决策API,这是一个全新的端点,由我们全新的Gemini Decision 1模型(gemini-decision-1)驱动,用于快速、闭集决策,可通过Google AI Studio中的Gemini API使用。
决策API为你提供专为有限选项场景打造的原子能力,例如工具选择、策略检查、模型路由和上下文分级。你可以传入一个跨文本、图像、音频、视频和PDF的多模态输入(最高256K token),同时附带最多1,000个独立问题。Gemini Decision 1不会逐token生成答案文本,而是在单次前向传播中对候选选项进行评分,返回概率和置信度分数,端到端延迟为150-250毫秒,价格为每100万输入token 0.10美元,输出token零计费。
强劲的性能与校准表现
在涵盖智能体路由、推理、排序和多模态理解的基准测试中,Gemini Decision 1全面领先,并具有最低的校准误差。
Gemini Decision 1无需逐token解码即可对选项评分,在多模态输入和不超过16K token的上下文下,模型计算的中位延迟保持在50-100毫秒(端到端150-250毫秒),且从每次请求1个问题到100个问题,延迟几乎持平。由于输出token零计费,在共享基准测试套件上,Gemini Decision 1配合决策API比Gemini 3.5 Flash-Lite配合Interactions API便宜近5倍。
原生多模态评估,一次请求覆盖三种决策类型
Gemini Decision 1基于Gemini原生多模态架构构建,可在单次前向传播中直接处理文本、图像、音频、视频和PDF。你可以在一个共享输入中组合多种模态,例如将通话录音与账户元数据配对,或将扫描的PDF理赔单与损坏照片配对,并可调整图像和视频输入的分辨率以控制视觉细节和token成本。
你可以在单次请求中针对该共享输入评估多个问题,混合使用是/否检查、多项选择和评分量表。每个答案都包含置信度分数(0到1),以便你的代码将模糊情况路由到回退方案或人工审核:
- noul(是/否):估计某个是/否条件成立的概率,可选提供true和false的描述标准。
- choice(多项选择):从2到255个选项中选择,返回获胜者及每个候选选项的归一化概率。
- score(有序评分量表):按照有序评分量表(从0开始)对输入进行评分,返回连续加权分数和每个等级的概率。
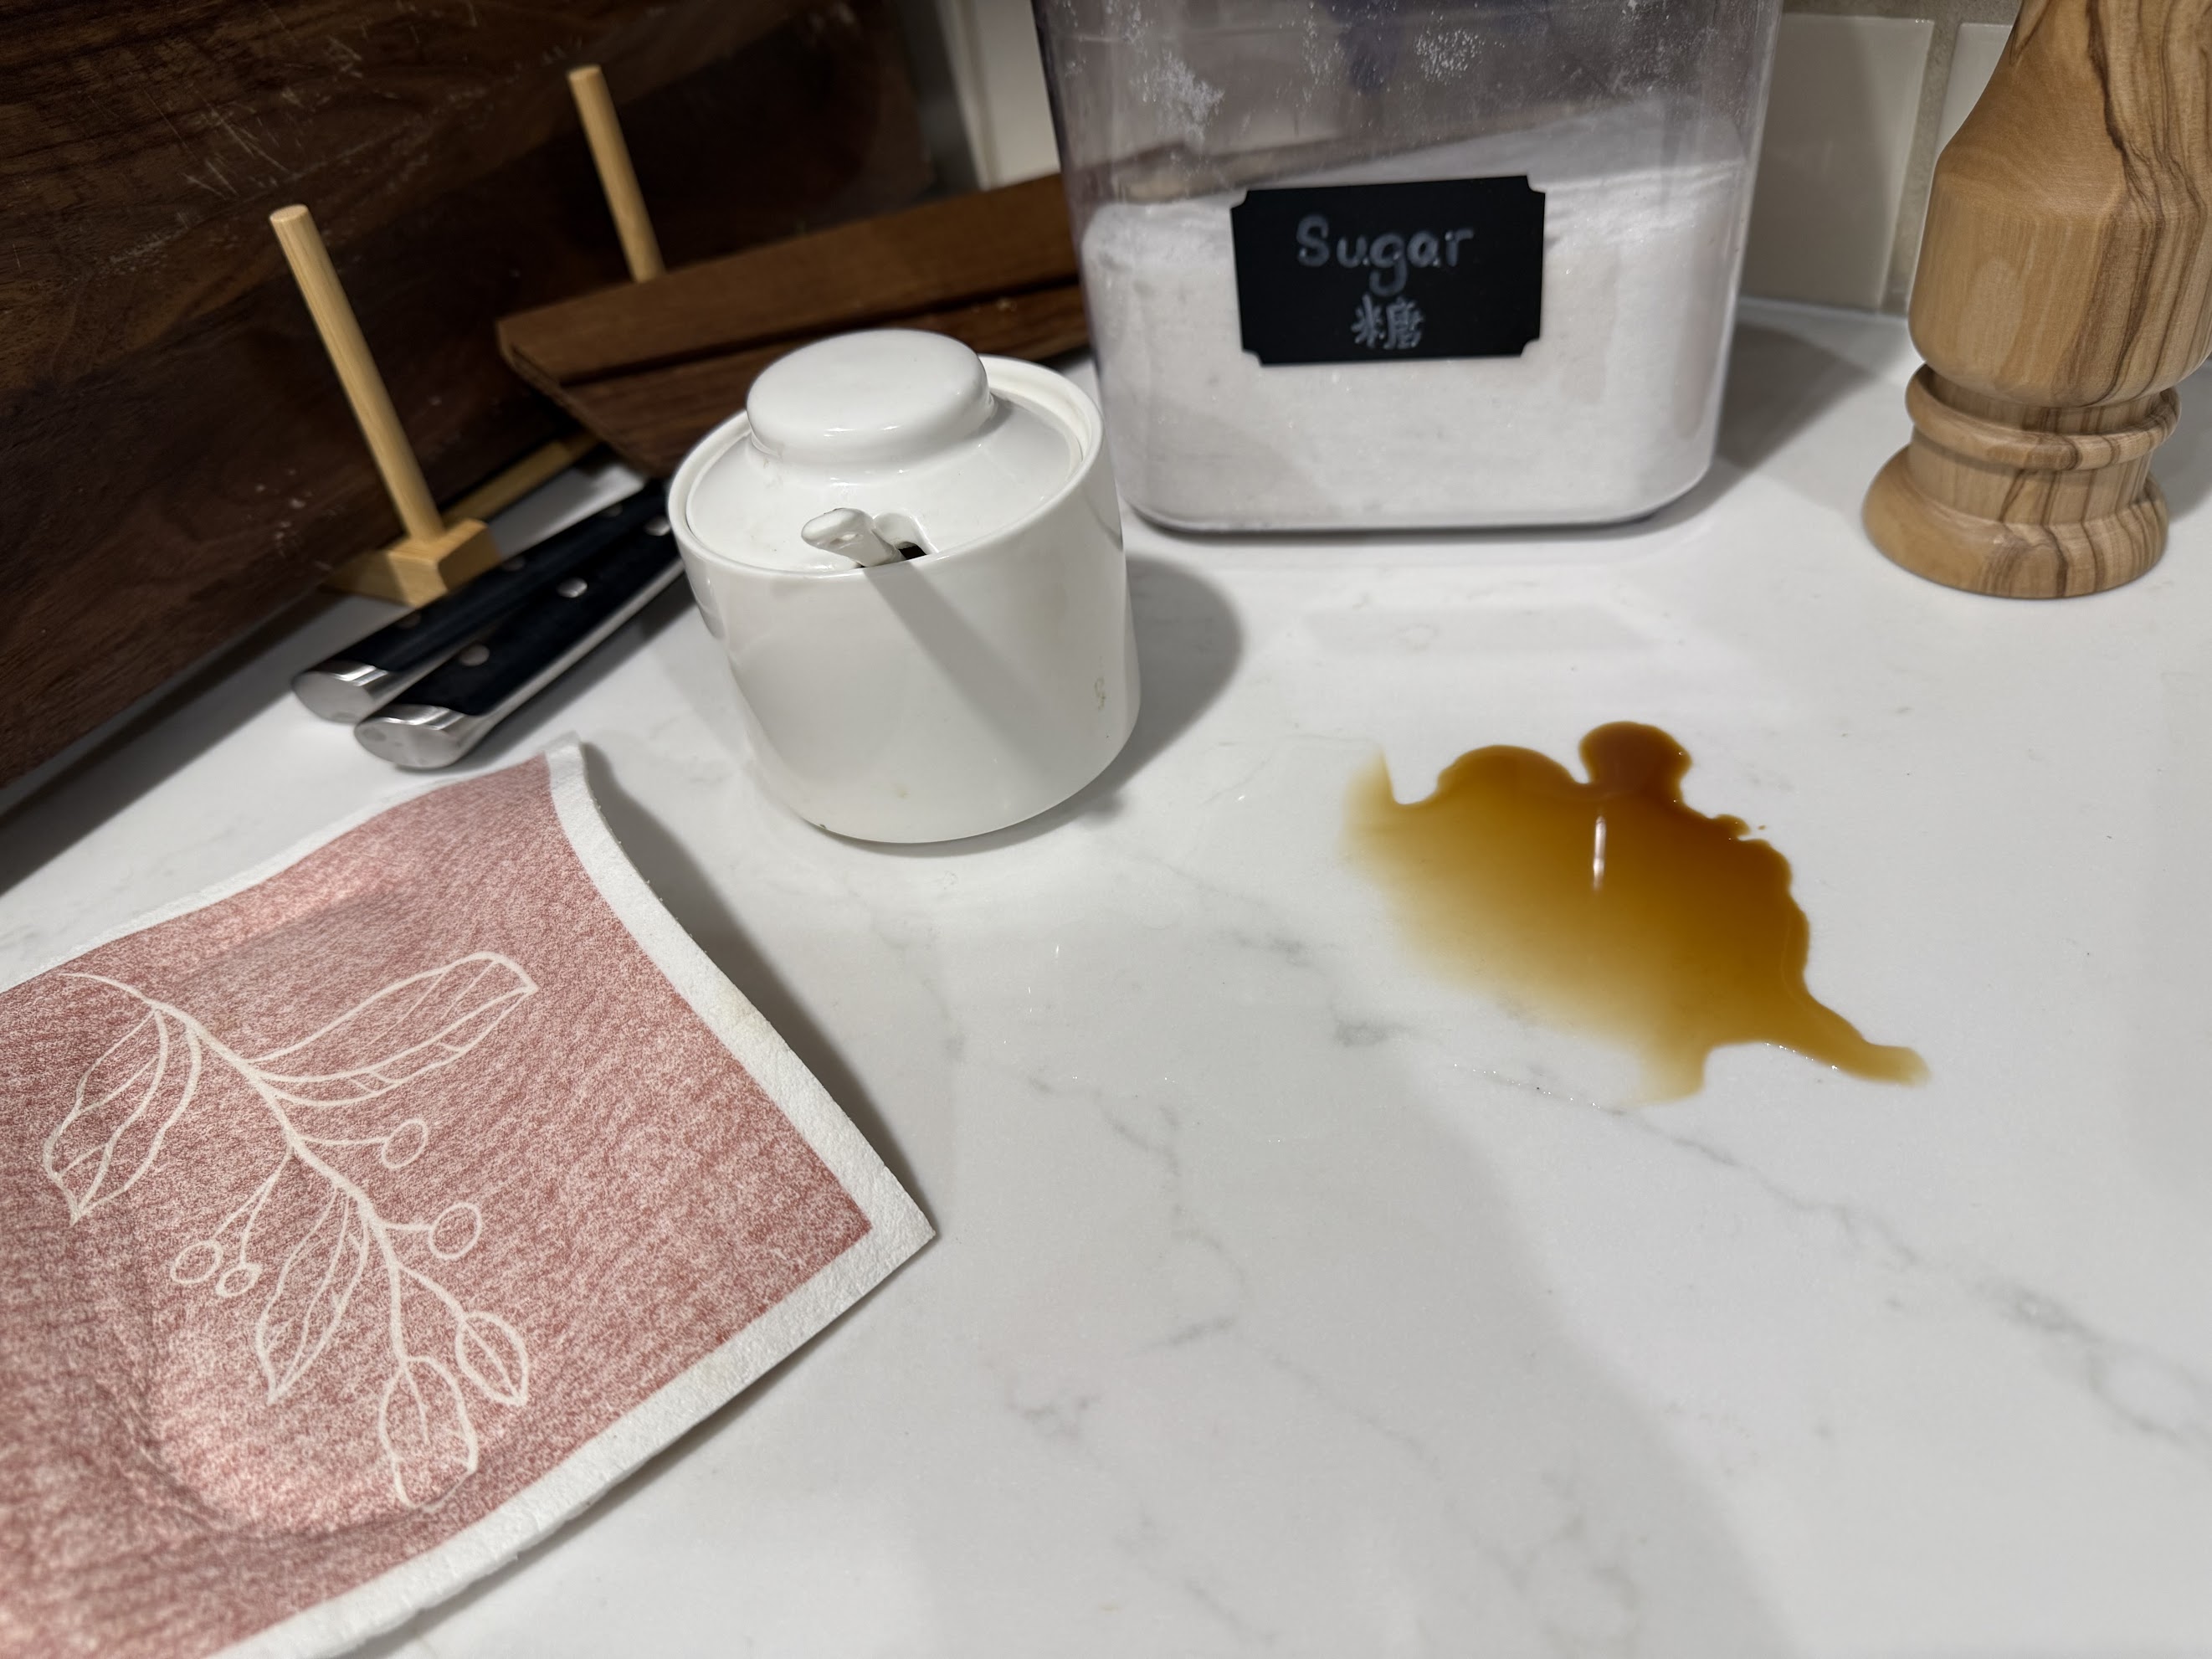
input字段使用与Interactions API相同的Content块格式。以下示例展示如何在单次请求中,将一张茶水间台面的照片连同一条文字备注,对照全部三种问题类型进行检查:
from google import genai
client = genai.Client(http_options={"api_version": "v1beta"})
result = client.decisions.create(
model="gemini-decision-1",
input=[{
"type": "image",
"uri": "https://storage.googleapis.com/generativeai-downloads/images/spill.jpg",
"mime_type": "image/jpeg",
},
{
"type": "text",
"text": "上午9点客户会议前的茶水间台面检查。",
},
],
questions={
"has_spill": {
"type": "noul",
"instructions": "台面上是否有未清理的液体泼洒?",
},
"next_action": {
"type": "choice",
"instructions": "哪种清理措施适合当前场景?",
"criteria": {
"wipe_with_cloth": "台面少量泼洒,附近已有抹布或毛巾。",
"dispatch_janitorial": "大面积地面危险、碎玻璃或持续泄漏。",
"ready_for_meeting": "台面干净,已准备就绪。",
},
},
"severity": {
"type": "score",
"instructions": "评估台面脏乱程度的严重性。",
"criteria": [
"干净,已准备就绪。",
"轻微局部泼洒。",
"严重泼洒或安全隐患。",
],
},
},
)
各团队如何借助决策API构建应用
Google内部的多个团队已将决策API用作低延迟控制平面,只需定义选项即可交付功能,无需训练自定义分类器或等待生成式调用:
- Gemini Notebook中的动态模型路由:Gemini Notebook将决策API用作实时路由器,即时将传入查询定向到最适合每个请求的模型层级和思考级别。决策API在毫秒内完成意图分类,使日常查询的延迟降低最多40%,同时将深度推理模型保留给复杂任务。
- Stitch中的快速设计迭代:Stitch全新的快速画布实验使用决策API在数秒内生成产品流程的可交互线框图,并几乎即时应用通过语音或点击做出的编辑。当流程感觉合适时,一键即可将屏幕移交到完整的Stitch体验中进行更深入的设计打磨。
- CC中的表情符号选择:Google Labs的CC使用决策API从200多个选项的调色板中在几分之一秒内挑选合适的表情反应,让反应即时出现且不增加延迟。
- 搜索中MCP工具的安全层:Google搜索使用决策API在延迟预算内高效检测对抗性行为和内容,对照对抗性评估表现优异。
Stitch Rapid使用决策API在数秒内设计完整的产品流程(1倍速)。
立即开始构建
Gemini Decision 1的定价为每100万输入token 0.10美元,输出token 0美元,并提供API免费层级,可在Google AI Studio中用于原型开发。无论你评估多少个问题,共享input每次请求仅计费一次(每个问题仅增加其自身的指令和标准token)。没有输出token费用、可变思考token账单,也没有单独的音频转写和OCR费用。
你可以立即开始构建:在Google AI Studio中获取API密钥,试用我们的Doorstep Parcels、Speed Sketch和Find the Zoo Keeper演示应用,并按照决策API文档中的Python、JavaScript和REST指南进行操作。
生态集成正在陆续登陆OpenRouter、LangChain、Vercel、LiteLLM、Pydantic AI、Pipecat、LiveKit和OpenCode,同时提供google-genai SDK,Google Cloud中的Gemini支持也即将推出。
英文来源:
Gemini Decisions API: Fast, calibrated multimodal decisions
Today, we’re introducing the Gemini Decisions API, a new endpoint for fast, closed-set decisions powered by our new Gemini Decision 1 model (gemini-decision-1), available through the Gemini API in Google AI Studio.
The Decisions API gives you purpose-built primitives for bounded choices like tool selection, policy checks, model routing, and context grading. You can pass one multimodal input across text, images, audio, video, and PDFs (up to 256K tokens) along with up to 1,000 independent questions. Rather than generating answer text token by token, Gemini Decision 1 scores your candidate options in a single forward pass, returning probabilities and confidence scores in 150-250 ms end-to-end latency at $0.10 per 1M input tokens with zero output tokens billed.
Strong performance and calibration
On benchmarks spanning agent routing, reasoning, ranking, and multimodal understanding, Gemini Decision 1 leads across the suite, with the lowest calibration error.
Gemini Decision 1 scores options without token-by-token decoding, keeping median latency 50-100 ms of model compute (150-250 ms end-to-end), across multimodal inputs and contexts up to 16K tokens, remaining nearly flat from 1 to 100 questions per request. With zero output tokens billed, Gemini Decision 1 with the Decisions API is nearly 5x cheaper across the shared benchmark suite than Gemini 3.5 Flash-Lite with the Interactions API.
Native multimodal evaluation across three decision types in one pass
Built on Gemini’s native multimodal architecture, Gemini Decision 1 can process text, images, audio, video, and PDFs directly in a single forward pass. You can combine modalities in one shared input, such as pairing a call recording with account metadata or a scanned PDF claim with damage photos, and tune resolution on image and video inputs to control visual detail and token cost.
You can evaluate multiple questions against that shared input in a single request, mixing yes/no checks, multiple choice, and rubric scores. Every answer includes a confidence score (from 0 to 1) so your code can route ambiguous cases to a fallback or human reviewer:
- noul (Yes/No): Estimates the probability that a yes/no condition holds, with optional true and false description criteria.
- choice (Multiple Choice): Selects from 2 to 255 choices, returning the winner and normalized probabilities for every candidate.
- score (Ordered Rubric): Grades inputs across an ordered rubric (starting at 0), returning a continuous weighted score and per-level probabilities.
The input
field uses the same Content
block format as the Interactions API. Here is how to check a photo of a breakroom counter, together with a text note, against all three question types in one request:
from google import genai
client = genai.Client(http_options={"api_version": "v1beta"})
result = client.decisions.create(
model="gemini-decision-1",
input=[{
"type": "image",
"uri": "https://storage.googleapis.com/generativeai-downloads/images/spill.jpg",
"mime_type": "image/jpeg",
},
{
"type": "text",
"text": "Breakroom counter check before the 9 AM client meeting.",
},
],
questions={
"has_spill": {
"type": "noul",
"instructions": "Is there an uncleaned liquid spill on the counter?",
},
"next_action": {
"type": "choice",
"instructions": "Which cleanup action fits the scene?",
"criteria": {
"wipe_with_cloth": "Small counter spill with a cloth or towel already nearby.",
"dispatch_janitorial": "Large floor hazard, broken glass, or active leak.",
"ready_for_meeting": "Counter is clean and ready.",
},
},
"severity": {
"type": "score",
"instructions": "Rate the severity of the counter mess.",
"criteria": [
"Clean and ready.",
"Minor localized spill.",
"Major spill or safety hazard.",
],
},
},
)
How teams are building with the Decisions API
Teams across Google are already using the Decisions API as a low-latency control plane, shipping features simply by defining options rather than training custom classifiers or waiting on generative calls: - Dynamic model routing in Gemini Notebook: Gemini Notebook uses the Decisions API as a real-time router to instantly direct incoming queries to the optimal model tier and thinking level for each request. The Decisions API classifies intent in milliseconds to serve everyday queries with up to 40% lower latency while reserving deep reasoning models for complex tasks.
- Rapid design iteration in Stitch: The new rapid canvas experiment in Stitch uses the Decisions API to generate playable wireframes of a product flow in seconds and to apply edits made by voice or tap almost instantly. When the flow feels right, one click hands the screens off to the full Stitch experience for deeper design polish.
- Emoji selection in CC: CC from Google Labs uses the Decisions API to pick the right emoji reaction from a palette of more than 200 options in a fraction of a second, so reactions appear instantly without adding latency.
- Safety layer for MCP tools in Search: Google Search uses the Decision API to detect adversarial behavior and content against adversarial evals with high efficacy within the latency envelope.
Stitch Rapid uses the Decisions API to design an entire product flow in seconds (1x speed).
Start building today
Gemini Decision 1 is priced at $0.10 per 1M input tokens and $0 for output tokens, with an API no-cost tier you can use in Google AI Studio for prototyping. Your shared input
is billed once per request no matter how many questions you evaluate (each question adds only its own instruction and criteria tokens). There are no output-token charges, variable thinking-token bills, or separate audio transcription and OCR costs.
You can start building today by grabbing an API key in Google AI Studio, trying our Doorstep Parcels, Speed Sketch, and Find the Zoo Keeper demo apps, and following the Python, JavaScript, and REST guides in the Decisions API documentation.
Ecosystem integrations are rolling out across OpenRouter, LangChain, Vercel, LiteLLM, Pydantic AI, Pipecat, LiveKit, and OpenCode alongside the google-genai
SDKs, with support coming soon to Gemini in Google Cloud.
文章标题:Gemini决策API:快速、经校准的多模态决策
文章链接:https://news.qimuai.cn/?post=5543
本站文章均为原创,未经授权请勿用于任何商业用途